9. Fundamentos de Aprendizado de Robôs e Aprendizado por Imitação
Capítulo 9 do Curso para Iniciantes em IA Física da Seeed — por que o braço precisa de aprendizado, controle baseado em regras vs. baseado em aprendizado, observação/estado/ação, blocos de ação, distribuição de dados e as três fases de treinamento, inferência e avaliação.
Hardware needed for this stage
What to prepare for this stage. The complete list for every stage is in Chapter 3.
Main control unit
| Item | Buy | Qty |
|---|---|---|
| reComputer Robotics J4012 | 🛒 | 1 |
| NVIDIA Jetson AGX Thor 128G | 🛒 | 1 |
A desktop or laptop is also required: Ubuntu 22.04, GTX 4080 or better with 12GB+ VRAM, 16GB+ RAM.
For this stage
| Item | Buy | Qty |
|---|---|---|
| reBot Arm B601 DM/RS | 🛒 | 1 |
| reBot Arm 102 Leader Arm | 🛒 | 1 |
| 720P Monocular Wrist Camera | 🛒 | 2 |
| Wrist Camera Mount | 🛒 | 1 |
| Hikvision Camera Overhead Mount | 🛒 | 1 |
9.1 Why Do Robot Arms Need Learning?
9.1 Why Do Robot Arms Need Learning?
In Stage 2, you can already control the robot arm with the Python SDK: read joint angles, send target positions, open and close the gripper. So it's natural to think — just write a program that makes the arm automatically pick up blocks on the table, right?
So you write such a program. During the first demo in the lab, the program worked great. But the next day, things changed — and you'll find that to handle these changes, more and more "if" statements get added to the program, eventually becoming a giant catalog of special cases that no one can maintain.
This is the fundamental dilemma of traditional programmatic control: the real world changes continuously, while if-else is discrete. You cannot enumerate every possible state of the world.
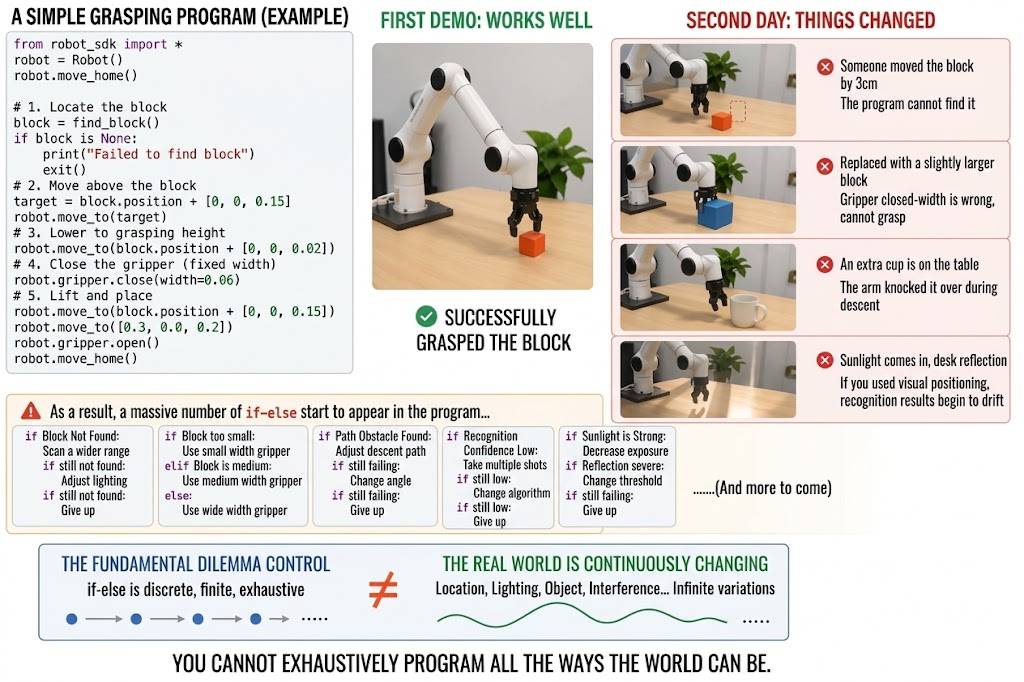
Enabling robot arms to acquire skills this way is what Robot Learning sets out to solve. And the imitation learning covered in this stage is the most mature and easiest-to-deploy-on-real-hardware approach.
9.2 Rule-Based Control vs. Learning-Based Control
9.2 Rule-Based Control vs. Learning-Based Control
Before continuing, let's put the two control approaches side by side and see them clearly.
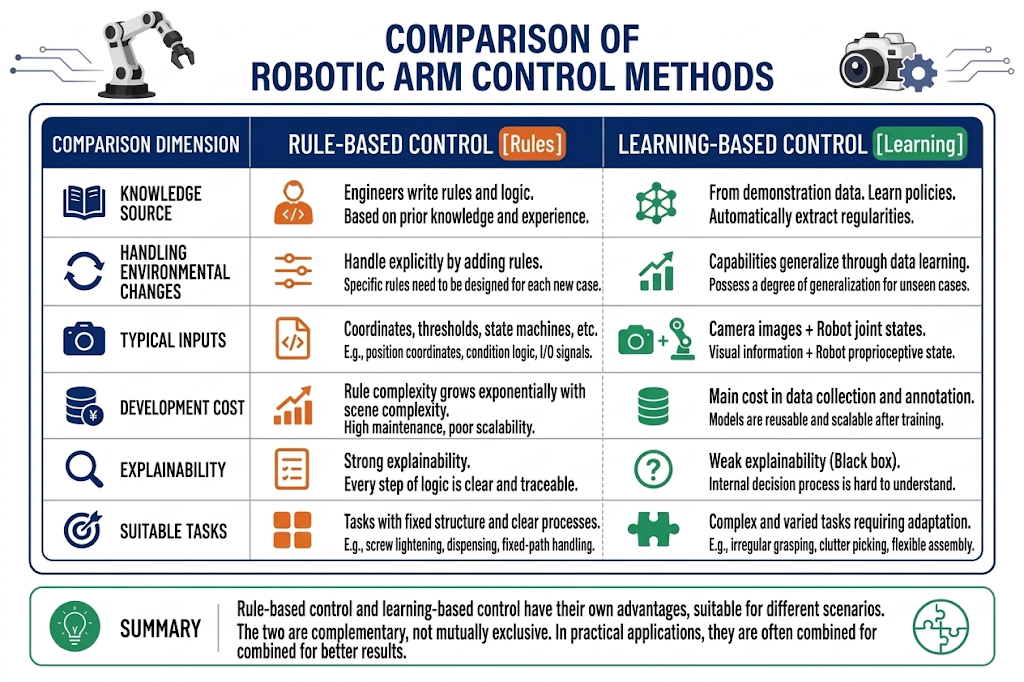
Stages 3 and 4 of this course follow the "learning-based control" path. But remember: even in the future, your learning systems will still retain a large number of rules — such as joint limits and safe speed constraints. Learning and rules are complementary.
9.3 Imitation Learning and Behavioral Cloning
9.3 Imitation Learning and Behavioral Cloning
What Is Imitation Learning
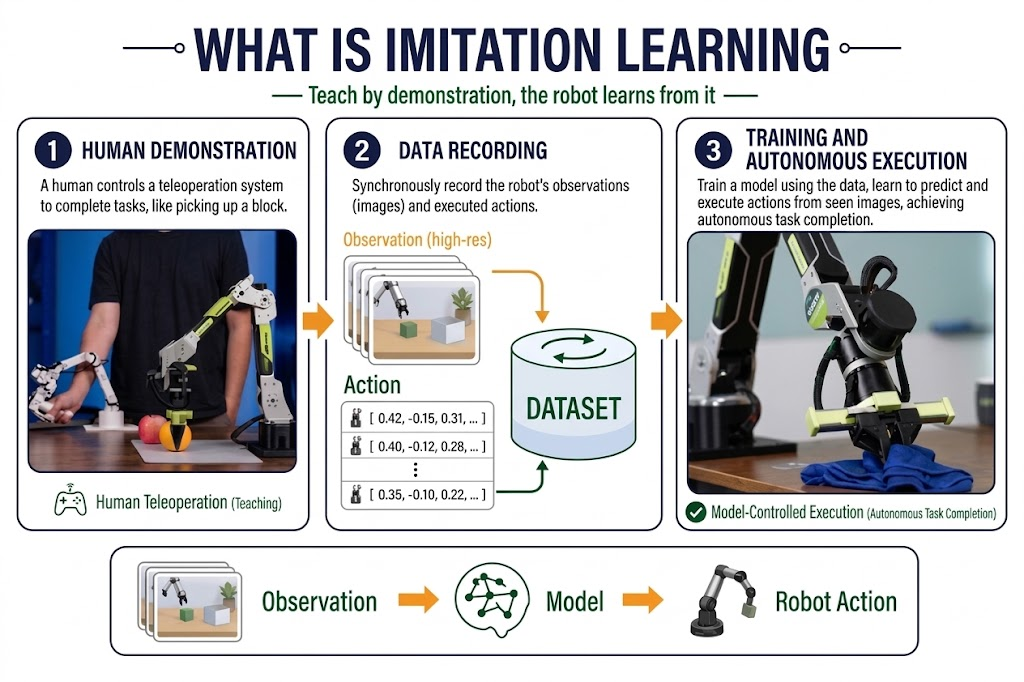
What Is Behavioral Cloning
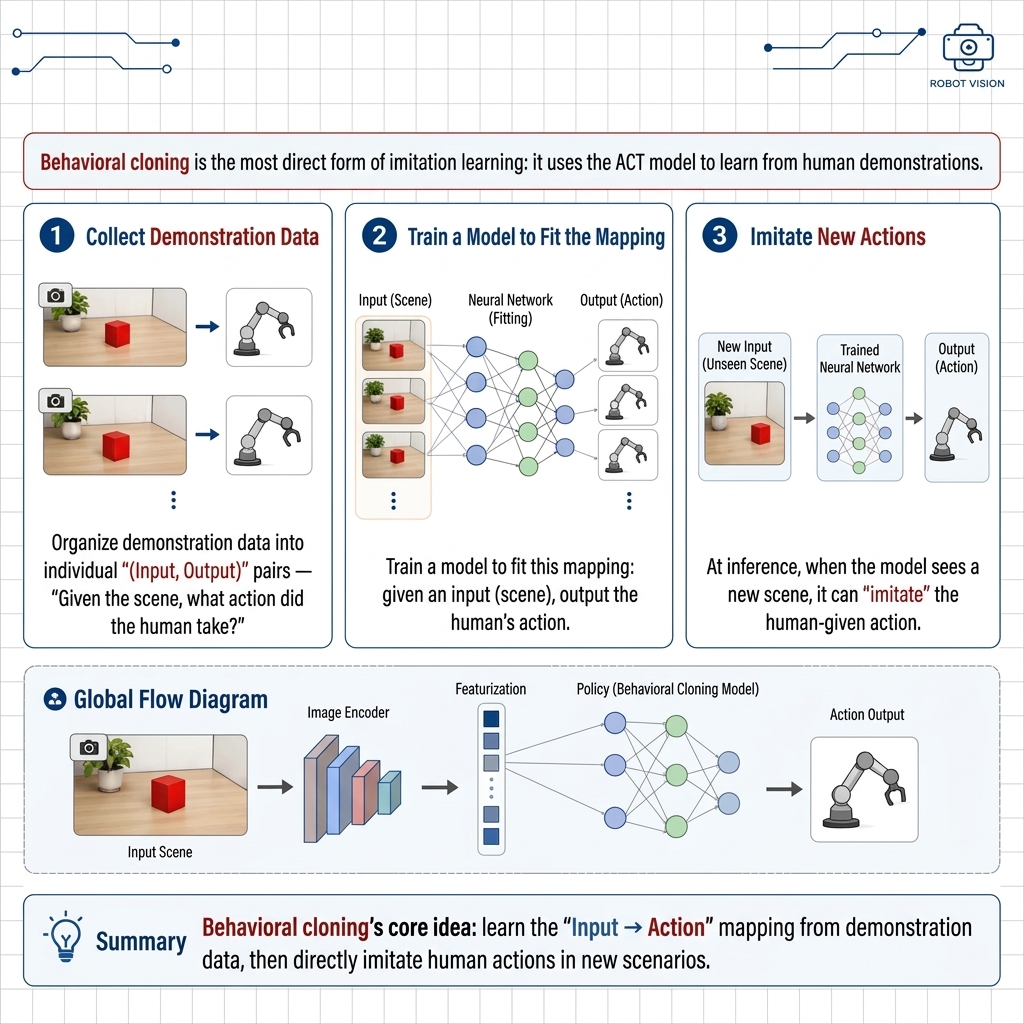
9.4 Observation, State, and Action
9.4 Observation, State, and Action
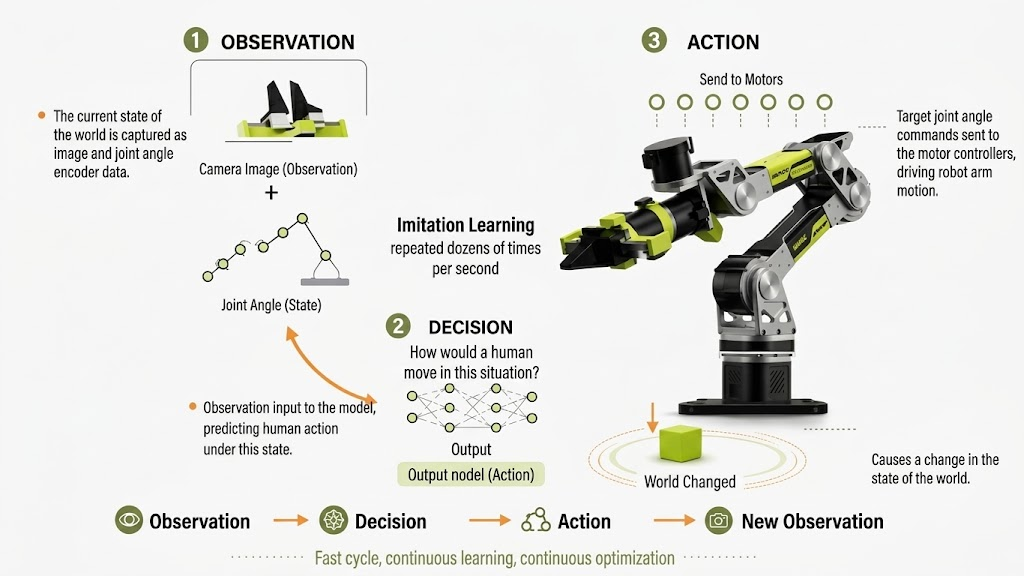
All data in imitation learning can be categorized into three concepts. These three terms will appear repeatedly in every chapter that follows, so build accurate intuition here.
- Observation: the world the robot "sees."
- State: the robot's "own" condition.
- Action: what the robot "will do."
9.5 Single-Step Actions vs. Action Chunks
9.5 Single-Step Actions vs. Action Chunks
- Single-step action: one decision per frame.
- Action chunk: predict a sequence of actions at once.
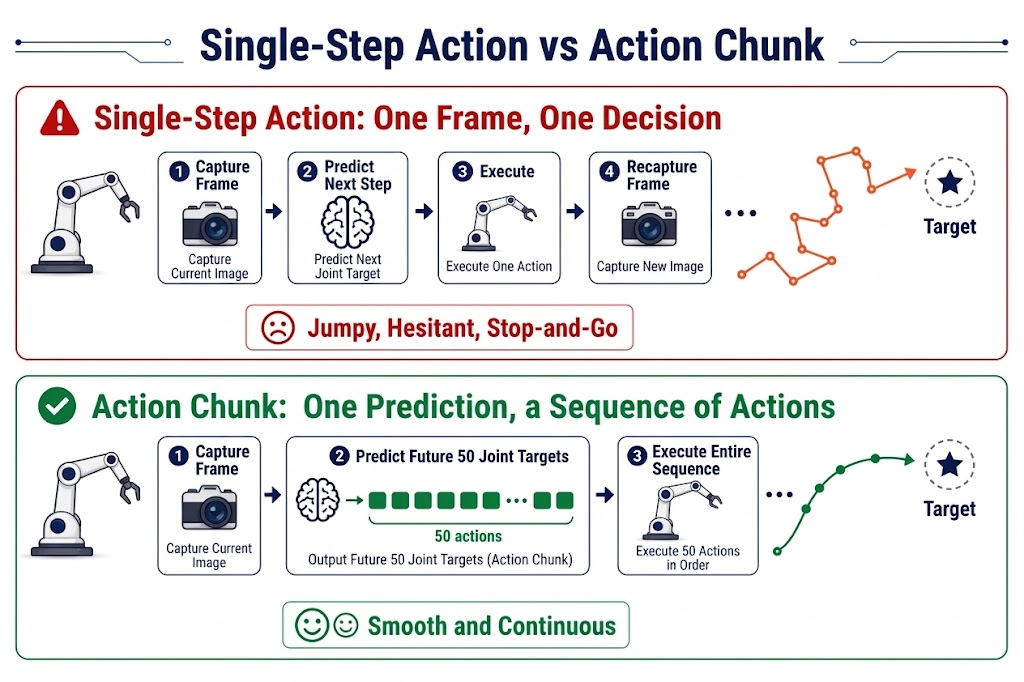
Of course, longer action chunks aren't always better. Predicting too far ahead means the environment may change mid-execution (e.g., an object gets bumped), while the arm is still executing "outdated" actions. Real systems use a compromise: execute open-loop for a short segment, then re-observe and re-predict.
9.6 Data Distribution and Model Generalization
9.6 Data Distribution and Model Generalization
This is the most important section of this chapter, and the one beginners most easily overlook, yet it determines success or failure in practice. Remember this one sentence first:
An imitation learning model can only learn what's in the data, and can only work within the range covered by the data.
- All (observation, action) pairs the model saw during training constitute a Data Distribution. During inference, if the images and states the arm encounters fall within this distribution, the model generally performs well; once they go outside the distribution, the model's output loses its basis and behavior becomes unpredictable.
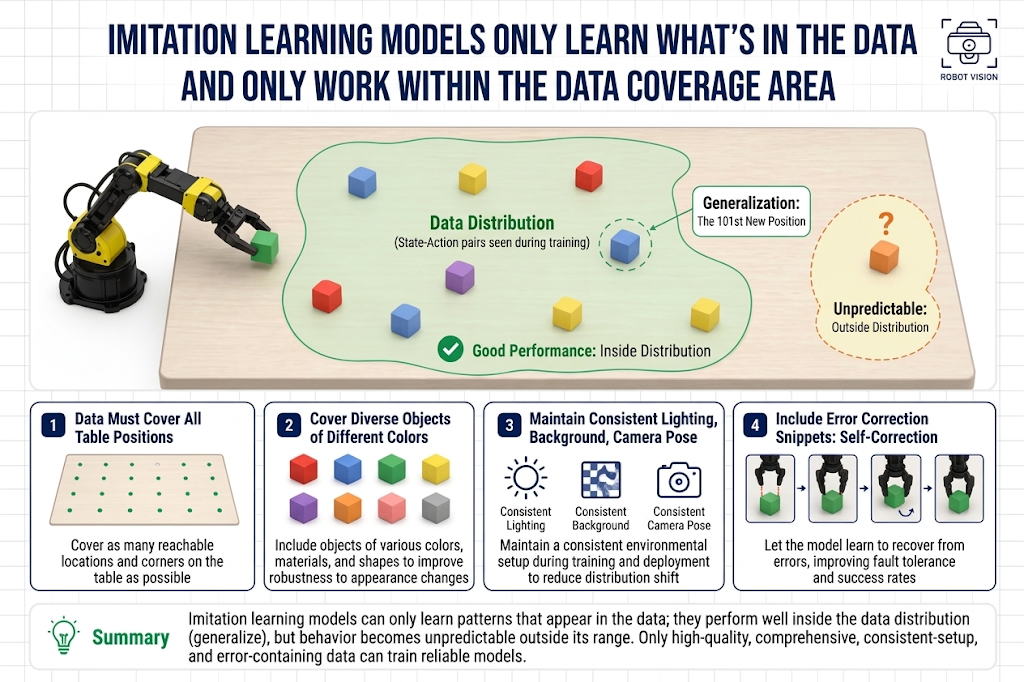
This leads to several very practical implications:
- If you want it to grasp blocks at any position on the table, the data must cover all positions on the table — if you only collect data at the center of the table, the model will only grasp at the center.
- If you want it to grasp objects of different colors, the data must contain different colors — otherwise, a new color is an unfamiliar world to it.
- Lighting, background, and camera position should all stay as consistent as possible with data collection — a model trained on afternoon-collected data may completely fail under evening indoor lighting.
And generalization is the model's ability to apply patterns learned from data to new situations within the distribution that it has not seen individually. For example, if training saw blocks at 100 different positions, and during inference a block appears at the 101st position (still on the tabletop), the model can still grasp it — that's generalization. Generalization isn't magic; it comes from the data's diversity: the richer and more continuous the data coverage, the smaller the "gaps" within the distribution, and the better the generalization.
The upper limit of imitation learning is essentially determined at the moment data is collected. Training merely realizes that upper limit.
9.7 Training, Inference, and Evaluation
9.7 Training, Inference, and Evaluation
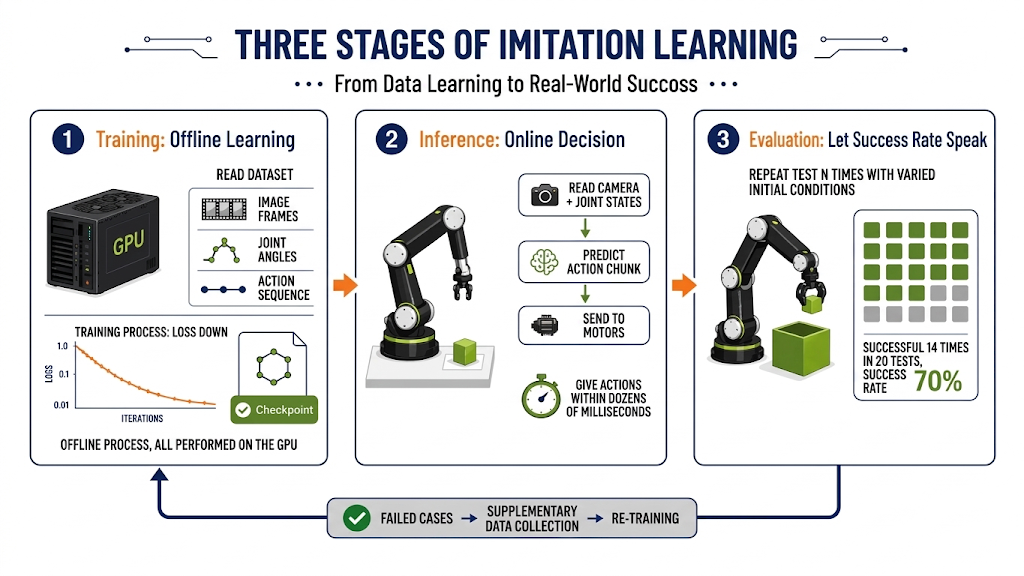
Training: Offline Learning
Training happens after data collection is complete; it's an offline process: the arm can be powered off and set aside; all work is done on the GPU.
- Input: collected dataset (time series of images, State, and Action);
- Process: the model repeatedly reads the data, continuously adjusting its internal parameters so that its predicted Actions increasingly match the human demonstrations;
- Output: a trained model file.
Training quality is primarily observed through Loss: as Loss decreases, the model's predicted actions increasingly resemble human demonstrations.
Inferência: Tomada de decisão online
Inferência é o processo em que o modelo é implantado no robô real e funciona em tempo real: lê os estados da câmera e das juntas → o modelo prevê um Action Chunk → envia-o para os motores para execução. A inferência tem requisitos de tempo real — o modelo deve gerar ações em dezenas de milissegundos, caso contrário o braço irá engasgar.
Avaliação: Julgado pela taxa de sucesso
O modelo é treinado, a Loss está baixa — ele realmente consegue fazer o trabalho? Não necessariamente.
Loss baixa só significa que o modelo é "parecido com o humano", não que ele "consegue completar a tarefa". O único método de avaliação confiável é o teste em robô real:
- Defina critérios claros de sucesso da tarefa (por exemplo, "o bloco termina dentro da caixa");
- Varie as condições iniciais (posição do bloco, iluminação), repita o teste N vezes;
- Calcule a taxa de sucesso da tarefa — por exemplo, 14 sucessos em 20 testes = 70% de taxa de sucesso.
Casos de falha encontrados durante a avaliação não são pontos finais; eles são insumo para a próxima rodada de coleta de dados — onde quer que ocorram falhas, colete dados adicionais ali e então re-treine. Este é o ciclo de iteração de dados, e é a rotina diária de projetos reais de aprendizado em robôs.
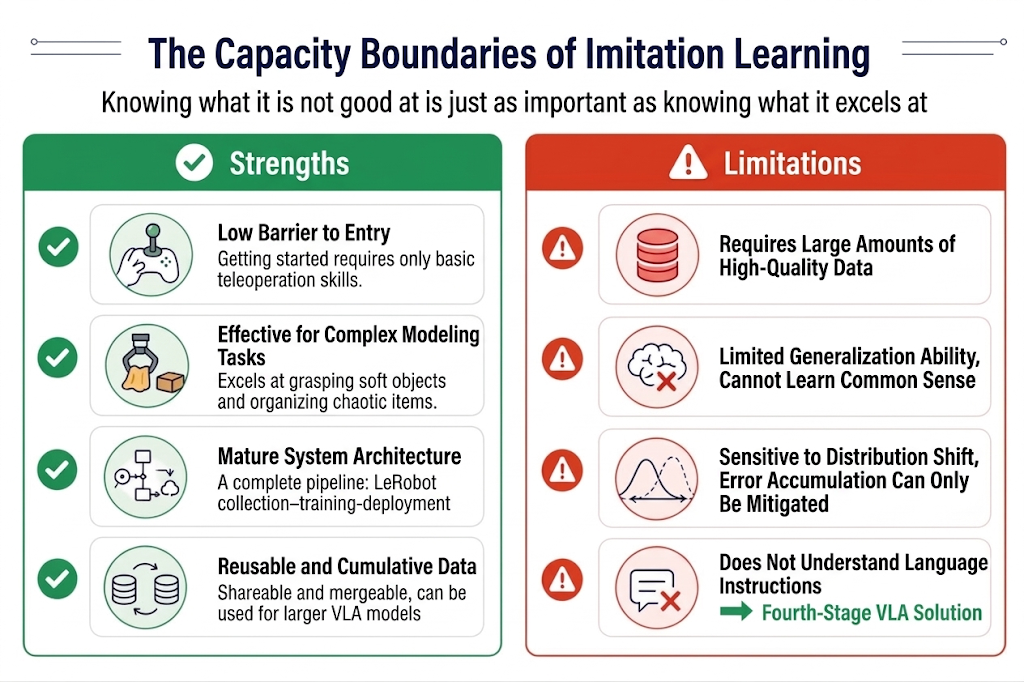
9.8 Vantagens e limitações do Imitation Learning
9.8 Vantagens e limitações do Imitation Learning