18. Multimodal Learning and VLA Basics
Chapter 18 of the SO-ARM Physical AI Beginner's Course — vision/language/action, VLM vs VLA, ACT vs VLA, language-conditioned tasks, single-task vs multi-task vs generalization, continuous actions vs action tokens, and VLA capabilities and limitations.
Hardware needed for this stage
What to prepare for this stage. The complete list for every stage is in Chapter 3.
Main control unit
| Item | Buy | Qty |
|---|---|---|
| NVIDIA Jetson AGX Thor 128G | 🛒 | 1 |
A desktop or laptop is also required: Ubuntu 22.04, GTX 4080 or better with 12GB+ VRAM, 16GB+ RAM (for GR00T fine-tuning, ~25GB VRAM — see 18.8).
For this stage
| Item | Buy | Qty |
|---|---|---|
| SO-ARM101 kit (Leader + Follower) | 🛒 | 1 |
| 32 × 32 mm USB camera | 🛒 | 2 |
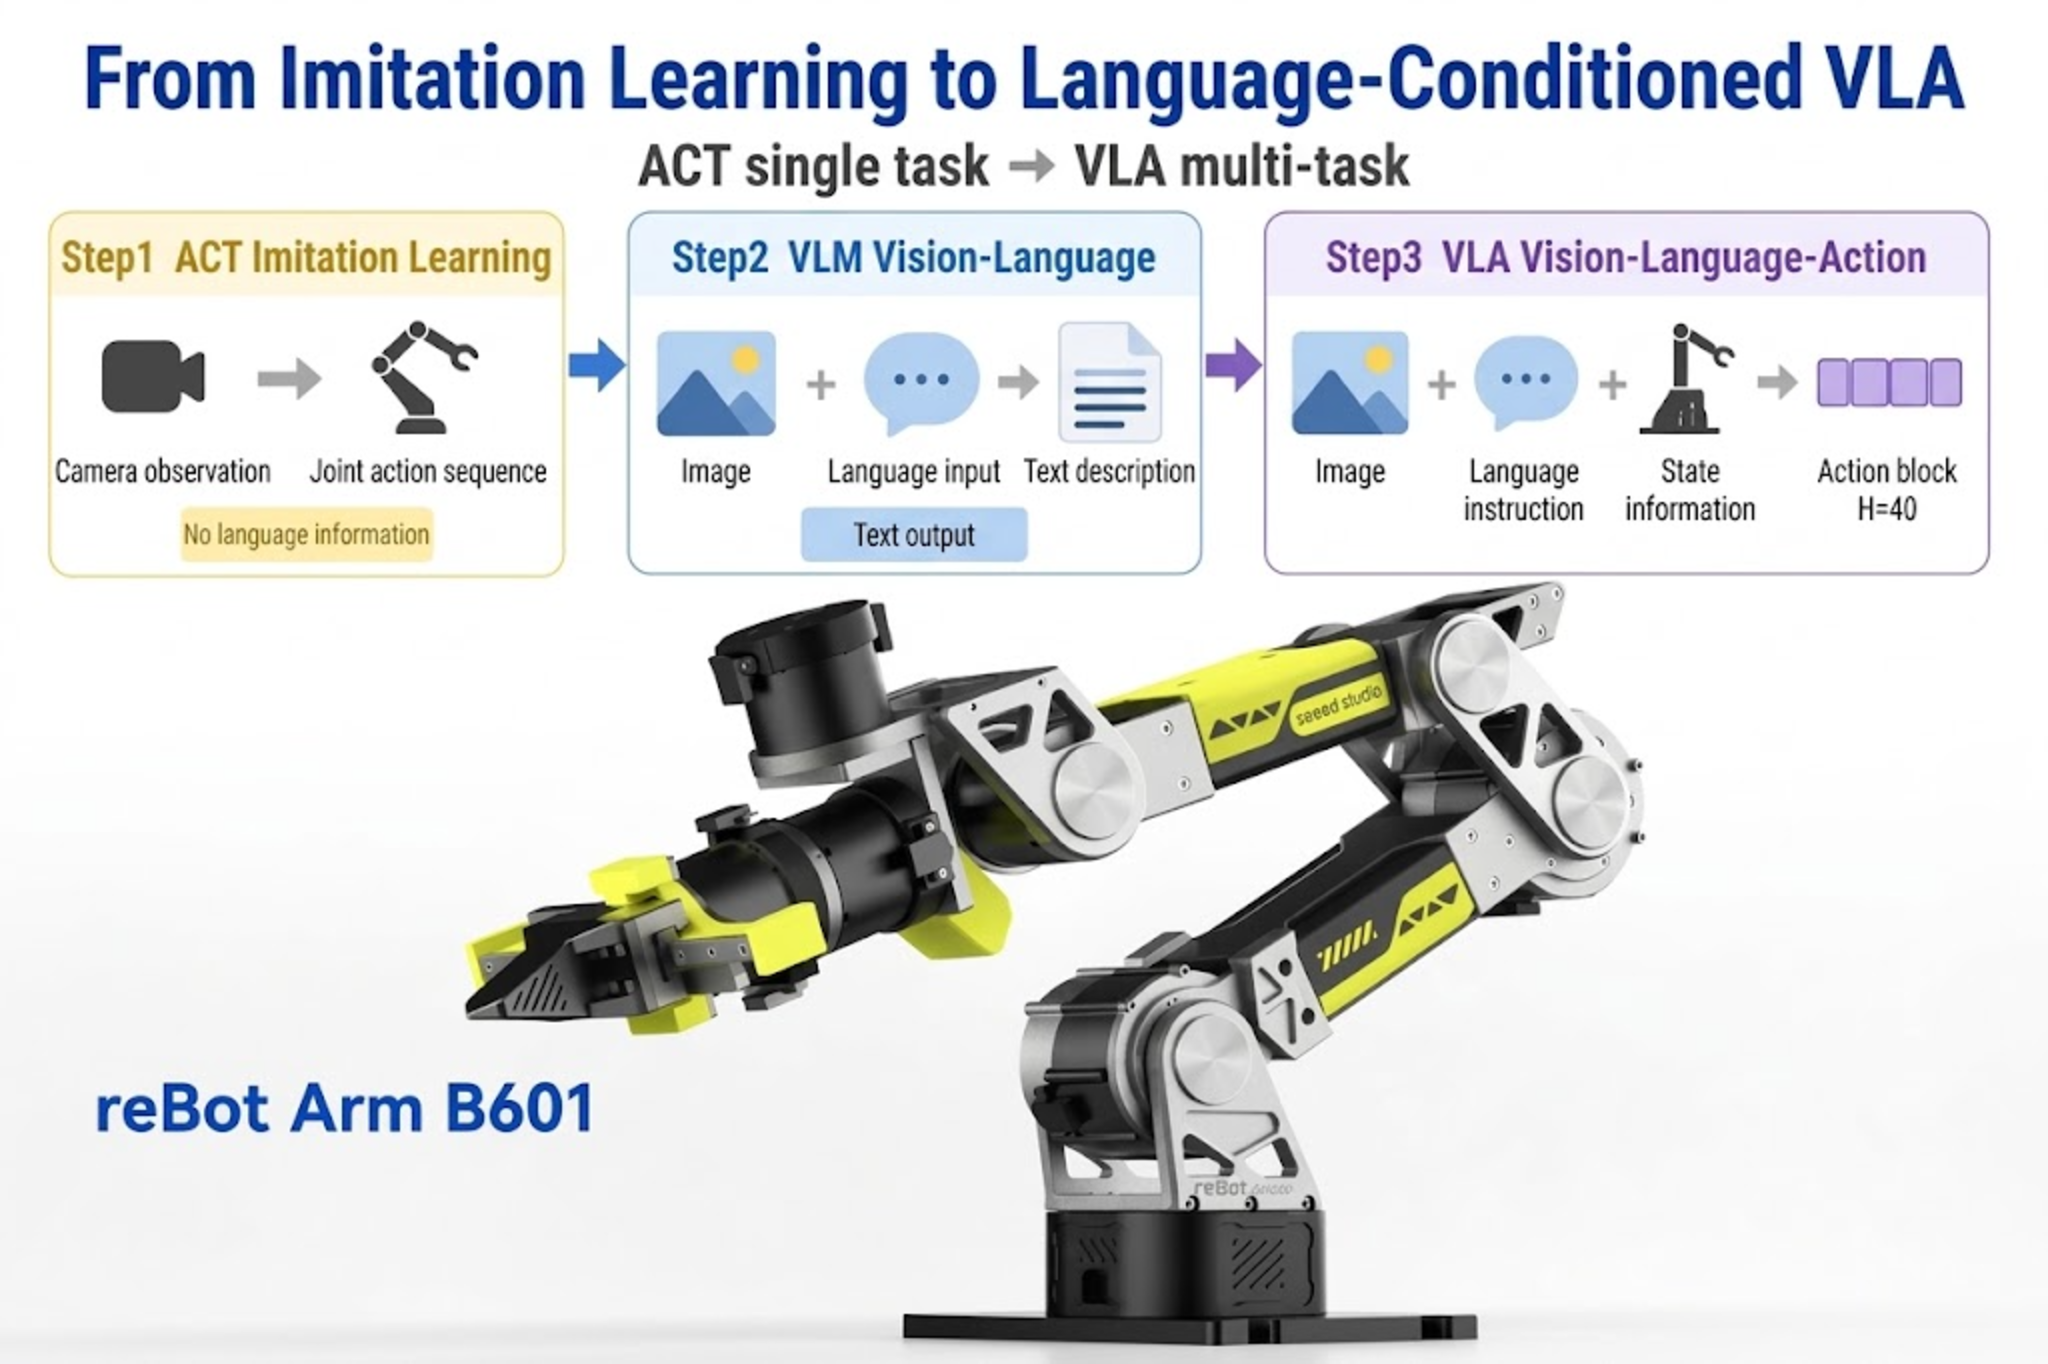
In the previous chapters, you have used policies such as ACT (Action Chunking with Transformers) on the SO-ARM to complete imitation learning that "looks at an image and outputs joint actions." Such methods are usually trained for a single task: the model only learns the single behavior of "putting the red cube into the box," and switching tasks requires recollecting data and retraining.
This chapter introduces the core idea of VLA (Vision-Language-Action): enabling the robot not only to "see" but also to "understand" natural language instructions, and to share one single policy network across multiple tasks.
18.1 Multimodal Models
18.1 What Is a Multimodal Model?
A multimodal model fuses more than one kind of information — images, text, and robot state — into a single unified decision. In the VLA context, the three modalities below are combined and decoded into robot actions.
18.2 Vision, Language, and Action
18.2 Vision, Language, and Action
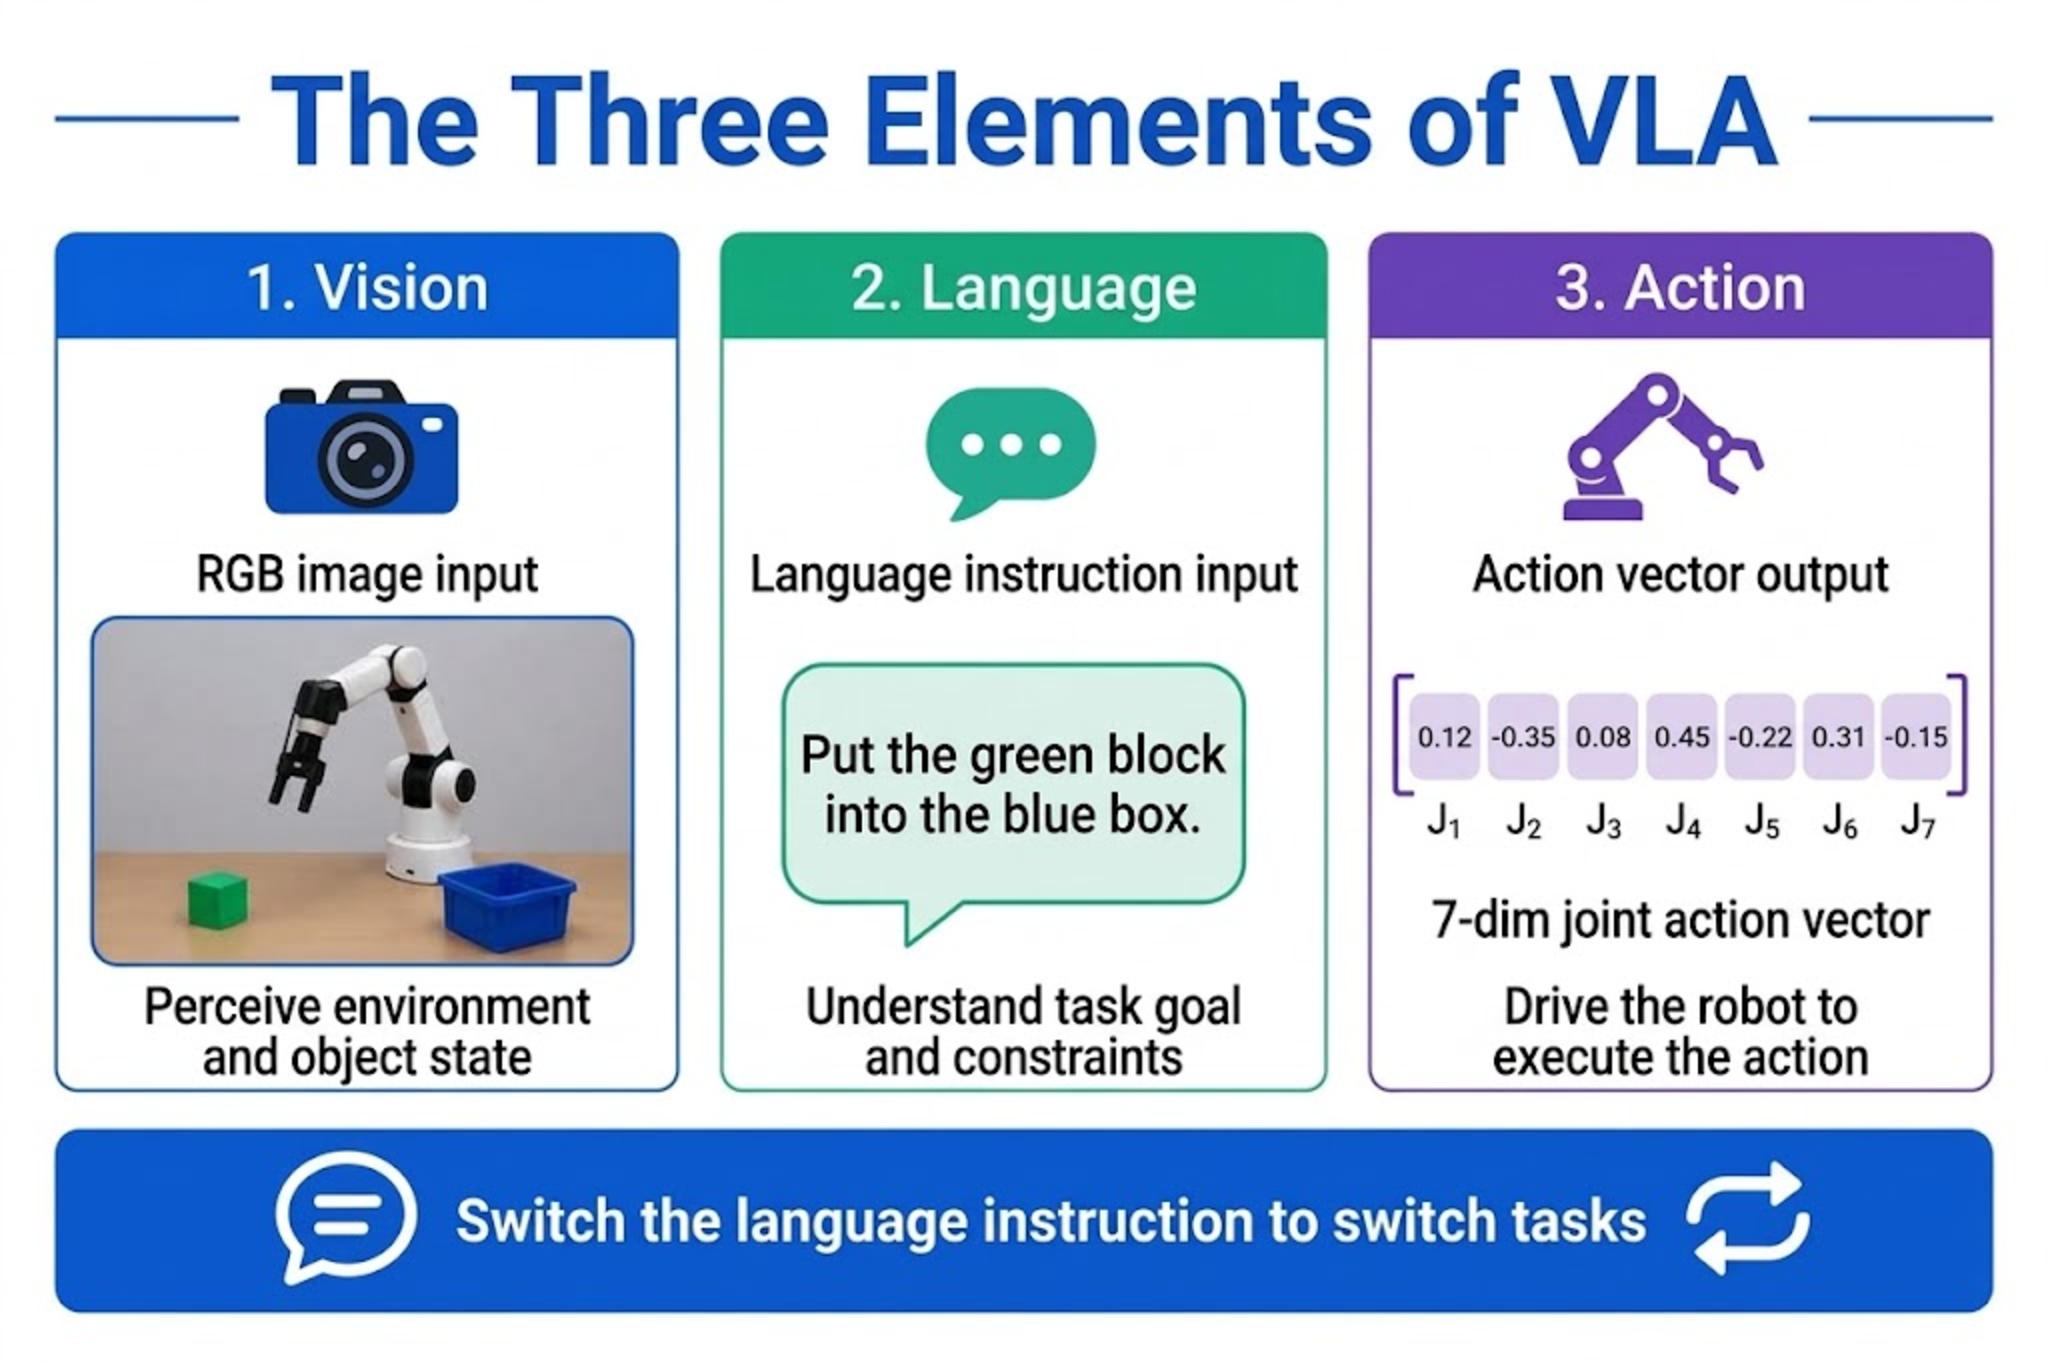
In the VLA framework, the three modalities each have a clear division of labor:
| Modality | Meaning | Typical source in SO-ARM |
|---|---|---|
| Vision | RGB images captured by external cameras | Front and side USB cameras |
| Language | Natural language description of the task | "Put the screwdriver into the toolbox" |
| Action | The control commands the robot must execute | Target angles of the 5 joints + gripper open/close width |
State usually appears in pairs with Action: State describes "where the robot is now," and Action describes "where to go next." In LeRobot datasets, they are stored in the observation.state and action fields; in GR00T they are further split via meta/modality.json into sub-keys such as state.single_arm and state.gripper.
The key difference between VLA and pure-vision policies: language becomes a conditioning variable. During training, every demonstration trajectory is bound to a task description; at inference time, the user only needs to change the instruction text, without changing the model weights (within data coverage).
18.3 Difference Between VLM and VLA
18.3 Difference Between VLM and VLA
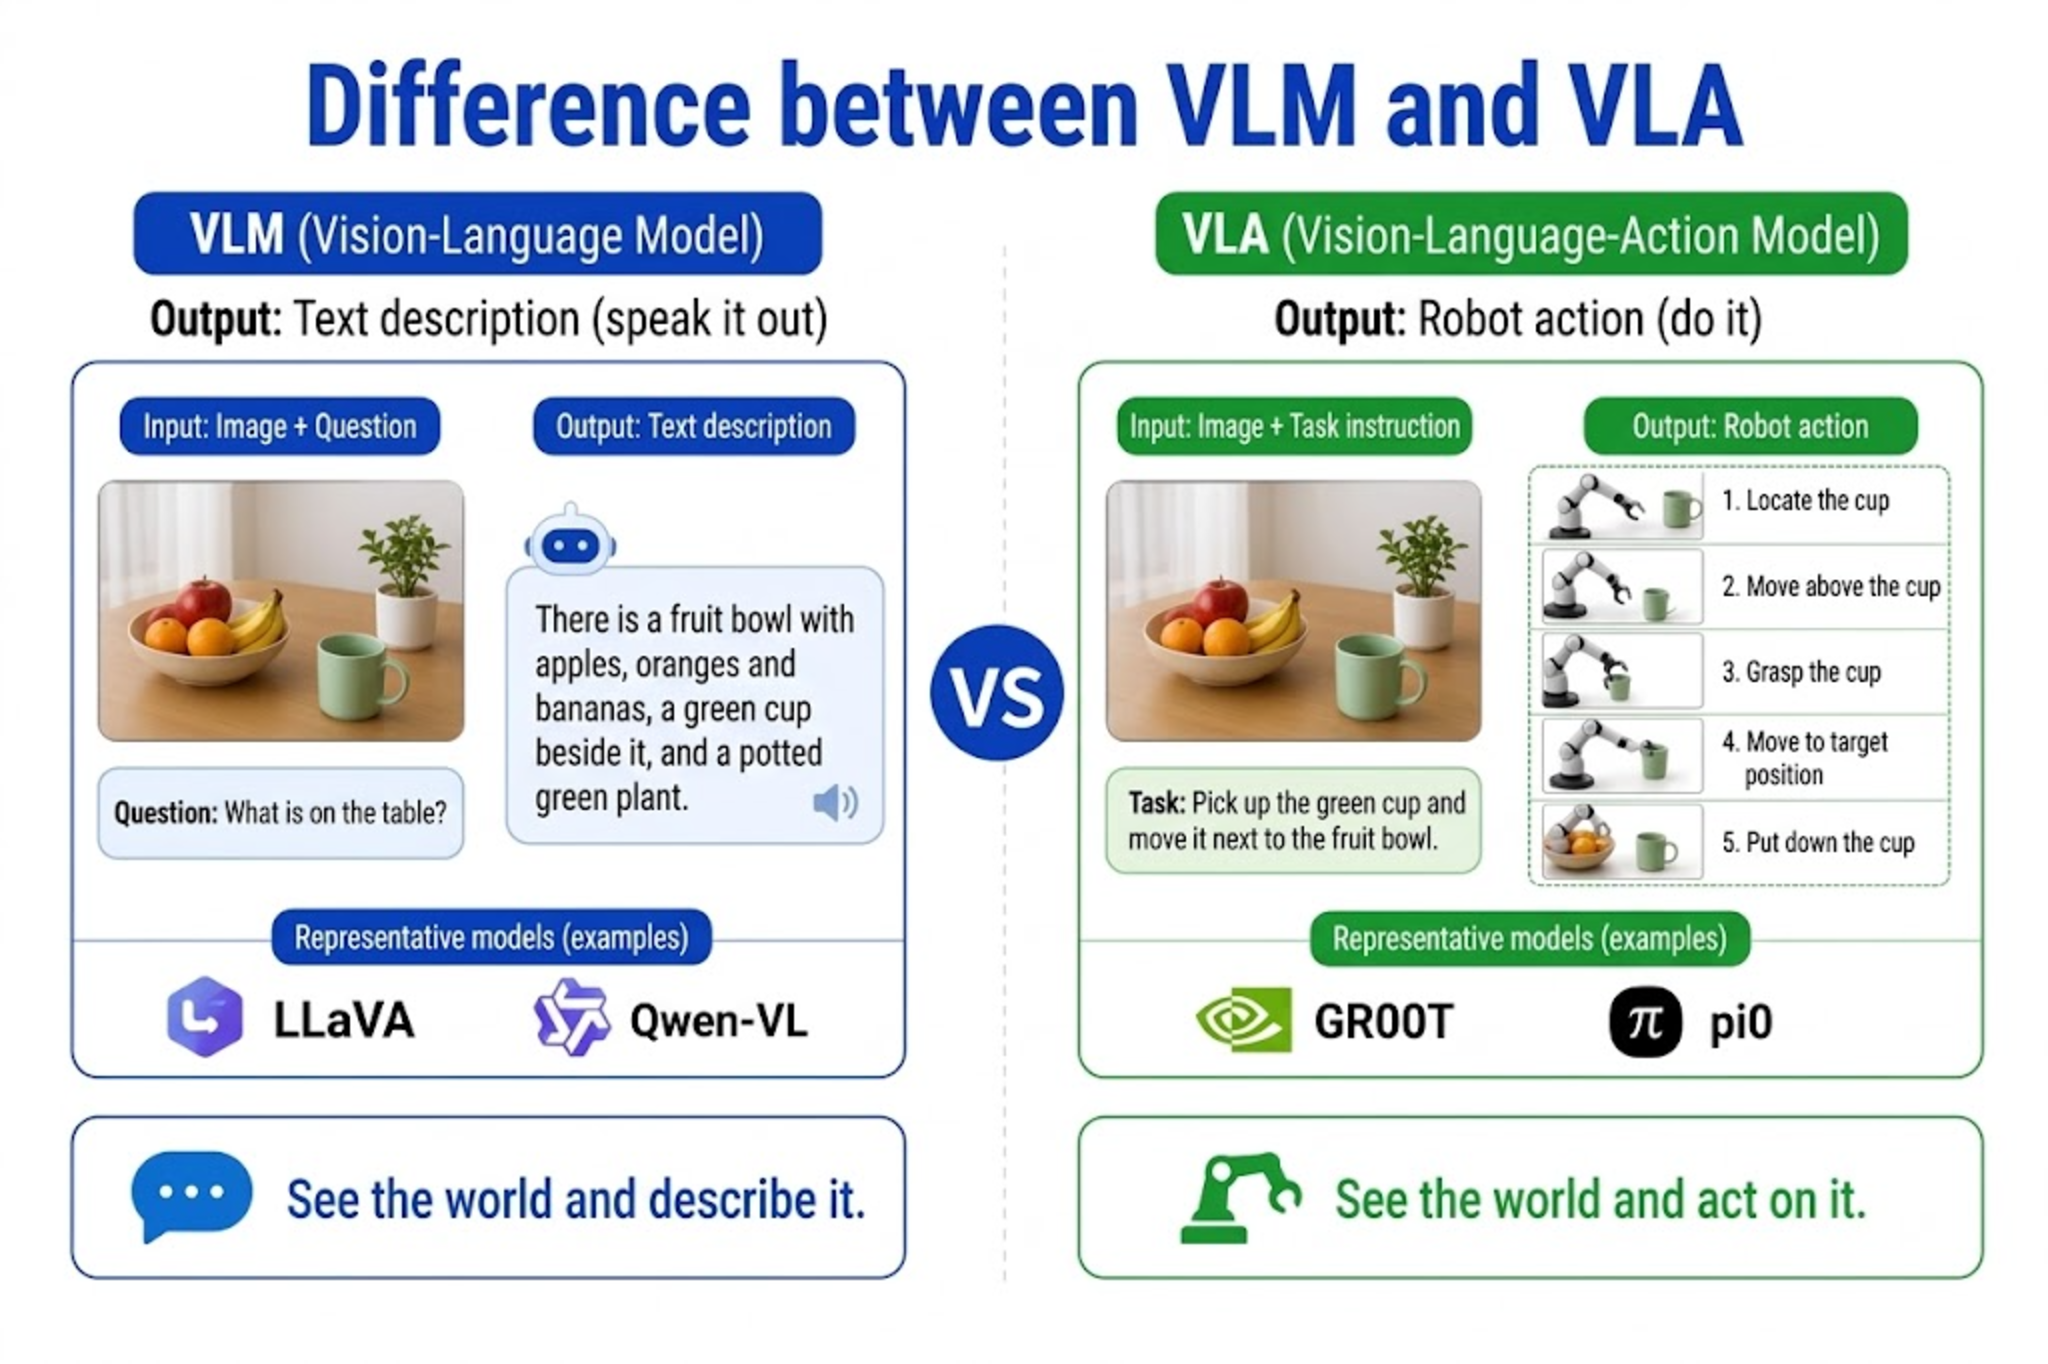
| Aspect | VLM (Vision-Language Model) | VLA (Vision-Language-Action) |
|---|---|---|
| Output | Text, descriptions, reasoning results | Robot action sequence |
| Typical use | Image QA, scene understanding, captioning | Grasping, placing, opening/closing doors, and other manipulation |
| Representative models | LLaVA, Qwen-VL, Cosmos-Reason | GR00T, pi0, OpenVLA |
| Relationship to robot | Can assist planning, does not directly drive motors | Outputs control commands end-to-end |
It can be understood simply as: VLM is responsible for "understanding the world and talking about it," while VLA is responsible for "understanding the world and taking action."
Isaac GR00T reuses VLM capabilities architecturally: a VLM backbone encodes images and language, followed by a Diffusion Transformer (DiT) action head that decodes semantic representations into continuous action chunks. Therefore GR00T is both a VLA and embeds strong VLM representation capabilities.
18.4 Difference Between ACT and VLA
18.4 Difference Between ACT and VLA
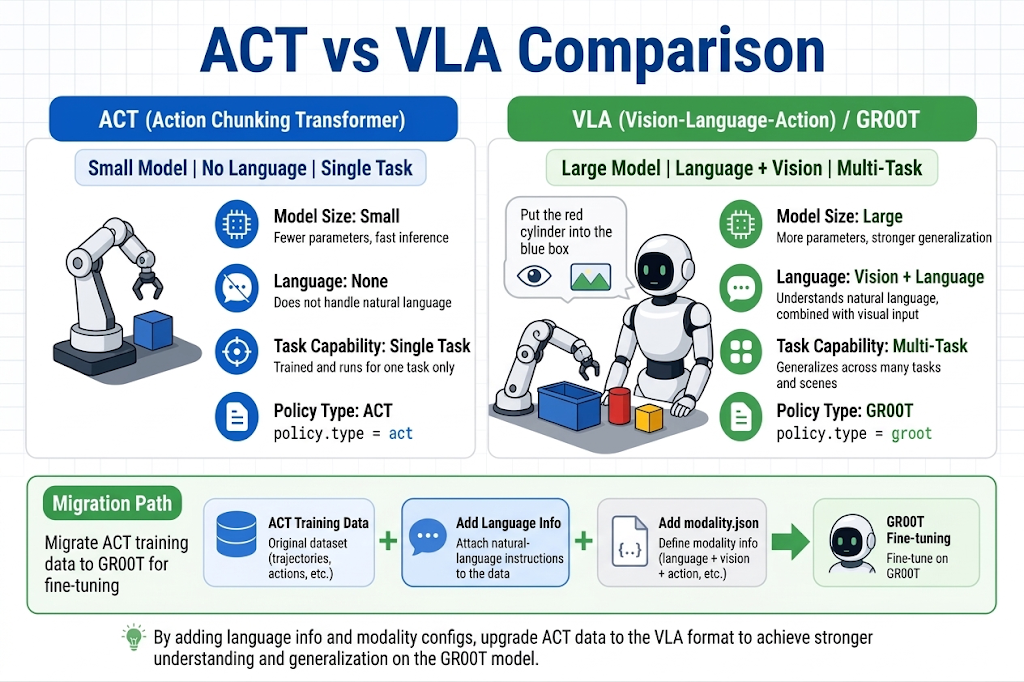
The ACT you encountered in previous chapters and the VLA in this chapter both belong to the imitation learning (Behavior Cloning) family, but their design goals differ:
| Aspect | ACT | VLA (GR00T as example) |
|---|---|---|
| Task condition | Usually no language, implicit single task | Language + vision, explicit multi-task |
| Model size | Smaller (tens of millions of parameters) | Larger (billions of parameter foundation model) |
| Training method | Train from scratch or light fine-tuning | Foundation model pretraining + downstream fine-tuning |
| Action representation | Action chunk | Action chunk + Flow Matching denoising |
| Generalization | Good within-distribution performance; retrain when switching tasks | Language conditioning supports zero/few-shot transfer |
| LeRobot policy type | act | groot |
The core technique of ACT is Action Chunking: predicting multiple future action steps at once to reduce accumulated error from step-by-step inference. GR00T also predicts action chunks (the window length varies by version — for N1.5, action_horizon = 16).
Migration path: if you already have an ACT dataset for the SO-ARM (LeRobot format), Chapter 20 only requires adding language annotations and Modality configuration before it can be used for GR00T fine-tuning, without recollecting all demonstrations.
GR00T N1.5 runs on the SO-ARM through the officially supported so100_dualcam data configuration and the new_embodiment tag — SO-ARM is one of the best-supported low-cost embodiments in the GR00T ecosystem, with an official SO101 fine-tuning guide from NVIDIA.
18.5 Language-Conditioned Robot Tasks
18.5 Language-Conditioned Robot Tasks
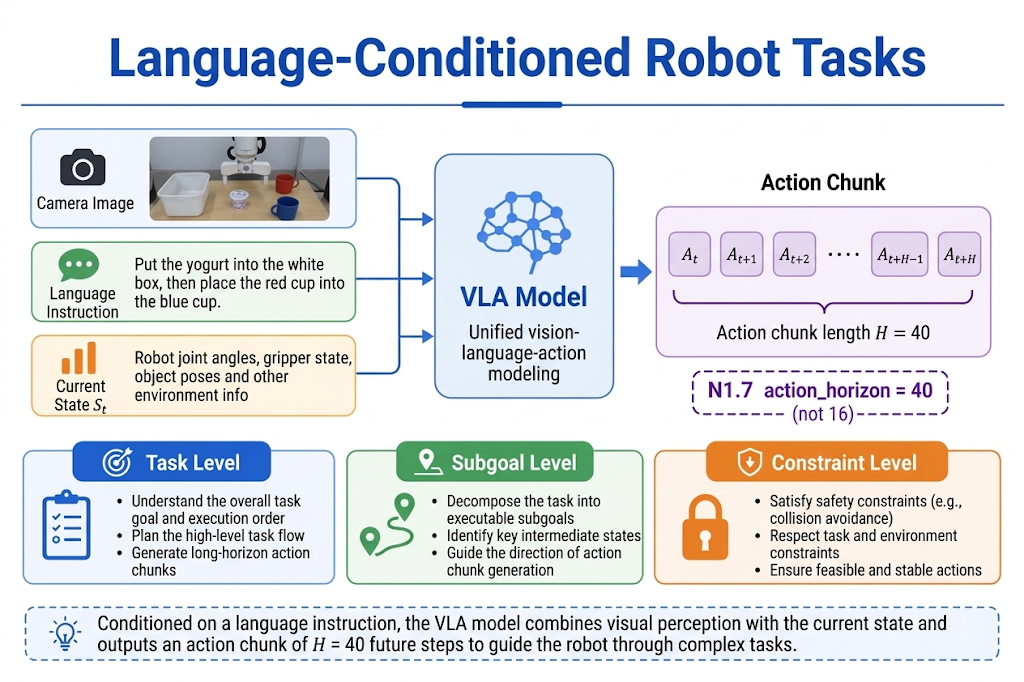
The standard form of a language-conditioned task is:
Input: image I_t + language instruction L + current state S_t
Output: actions A_{t:t+H} (action chunk for the next H steps)
Instruction granularity can vary:
- Task-level: "put the red cube into the blue box" (one sentence shared by the whole trajectory)
- Subgoal-level: "first approach the object" -> "then close the gripper" (segmented annotation, advanced scenarios)
- Constraint-level: "place gently," "avoid obstacles" (modifies how the action is executed)
In LeRobot datasets, language is usually written in the meta/tasks.jsonl or annotation field. GR00T reads it through the annotation key in modality.json; two common forms are:
| Key name | Typical datasets | SO-ARM recommendation |
|---|---|---|
human.task_description | SO-100 / SO101, cube_to_bowl, and other simple desktop tasks | Recommended: consistent with the Chapter 20 example |
human.action.task_description | LIBERO, SimplerEnv, and other simulation benchmarks | Use only if your data comes from these benchmarks |
Both keys are valid, but they must match the actual fields in the dataset; do not mix them between training and inference.
Practical advice (SO-ARM):
- When recording each demonstration, describe the task in one short, verb-first sentence in Chinese or English.
- Keep the phrasing consistent for similar tasks, e.g. uniformly use "put X on Y."
- Avoid having one data point correspond to multiple phrasings; the more consistent the better during early fine-tuning.
18.6 Single-Task, Multi-Task, and Generalization
18.6 Single-Task, Multi-Task, and Generalization
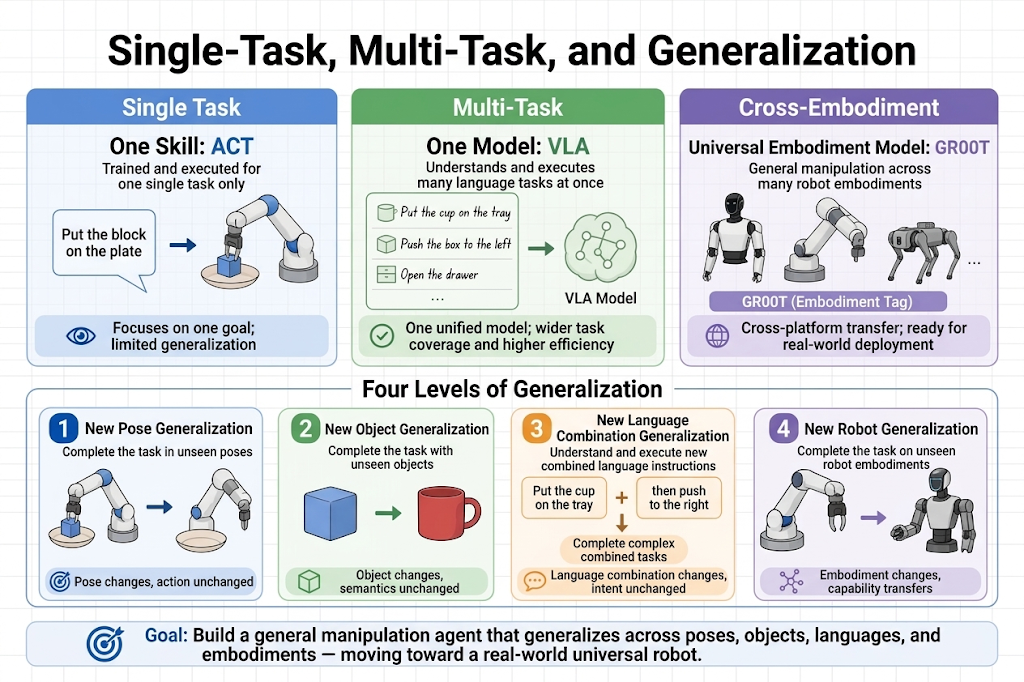
| Training paradigm | Description | Suitable scenarios |
|---|---|---|
| Single-task | Learns only one skill | ACT default; little data, clear objective |
| Multi-task | The same model learns multiple skills, distinguished by language | VLA fine-tuning; desktop tidying, sorting, etc. |
| Cross-embodiment generalization | Different robots share a foundation model | GR00T pretraining; adapted via embodiment_tag |
"Generalization" in VLAs has several levels — do not confuse them:
- Same task, new initial pose: can still grasp when the object position changes — ACT can usually do this too.
- New objects, new containers: relies on visual generalization — requires sufficient diversity in training data.
- New language instruction combinations: "put A on B" never seen before but the sentence pattern is familiar — the language-conditioning advantage of VLA.
- New robot embodiment: still usable when switching arms — requires GR00T's embodiment projection layer plus a small amount of fine-tuning data.
For SO-ARM users, the realistic expectation is: after fine-tuning, you can switch among the multiple language tasks already collected; for entirely new objects or entirely new sentence patterns, additional demonstration data is still needed.
18.7 Continuous Actions and Action Tokens
18.7 Continuous Actions and Action Tokens
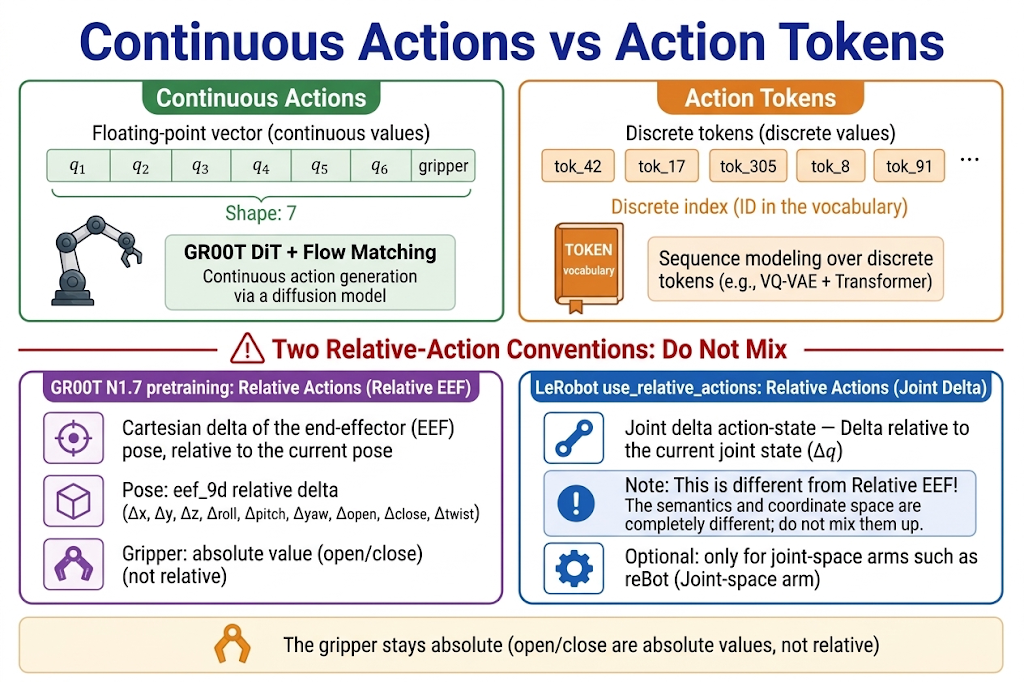
There are two mainstream representations for robot control commands:
Continuous Actions
Directly outputs a floating-point vector, e.g. 5 joint angles + 1 gripper open/close value:
action = [q1, q2, q3, q4, q5, gripper] # shape: (6,)
- Advantage: high precision, consistent with the real motor interface.
- Disadvantage: high-dimensional space regression is difficult.
- GR00T uses: DiT + Flow Matching to denoise in continuous space, outputting action chunks.
Action Tokens (Discretized Actions)
Quantizes continuous values into discrete symbols, like a language model predicting the next token:
action_tokens = [tok_42, tok_17, tok_89, ...]
- Advantage: can reuse autoregressive LLM architectures; adopted by some VLAs such as pi0-FAST.
- Disadvantage: quantization loss, complex vocabulary design.
Relative vs. absolute actions: GR00T's pretrained action space uses relative actions (increments with respect to the current state) for some embodiment groups and absolute joint positions for others; the gripper stays absolute. Relative trajectories are smoother, but long-term execution may drift. For SO-ARM fine-tuning you mostly rely on the defaults of the so100_dualcam data config — the takeaway is simply: don't hand-edit action-space transforms you don't understand.
18.8 Capabilities and Limitations of VLA
18.8 Capabilities and Limitations of VLA
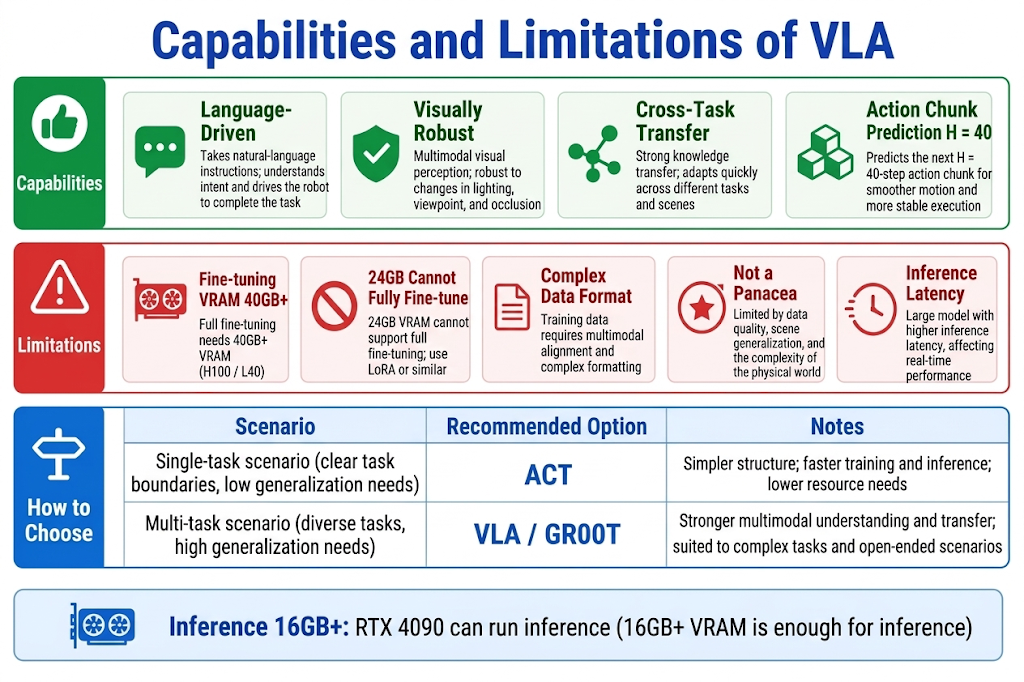
Capabilities
- Language-driven: one model, many tasks; switch behavior by changing the instruction.
- Visual robustness: large-scale pretraining brings better scene understanding than small ACT.
- Cross-task transfer: representations can be shared among similar sentence patterns and similar objects.
- Action-chunk prediction: one inference outputs multiple steps, suitable for real-time control.
Limitations
- High compute demand: GR00T N1.5-3B fine-tuning needs roughly 25GB of VRAM (Ampere or newer — e.g. RTX 4090 / A6000; V100 is not supported), and can be lowered with
--no-tune_diffusion_model. Inference is lighter and runs on Jetson AGX Thor (Chapter 21) — and Chapter 22 needs no GPU at all. - More complex data format: beyond standard LeRobot fields, a
modality.jsonand embodiment tag are required. - Not a panacea: objects, instructions, and workstation layouts not covered by the training set may still fail.
- Latency: large-model inference is slower than ACT; set the action window and inference parameters appropriately.
- Sim-to-real gap: pretraining data is dominated by specific platforms; desktop arms require sufficient fine-tuning.
When to Choose ACT, When to Choose VLA?
| Scenario | Recommendation |
|---|---|
| Single repetitive task, edge device, low latency | ACT |
| Multi-task, language interaction, willing to invest in GPU and annotation | VLA / GR00T |
| Already have ACT data, want to expand to multi-task | Add language to existing LeRobot data -> GR00T fine-tuning (Chapter 20) |
| No training GPU at all | No-code VLA on SenseCraft Robotics (Chapter 22) |
18.9 Chapter Summary
18.9 Chapter Summary
- Multimodal models fuse vision, language, and state into unified decisions.
- VLA adds action output on top of VLM, supporting language-conditioned manipulation.
- ACT is a lightweight single-task solution; GR00T is a large-scale pretraining + fine-tuning VLA solution.
- The SO-ARM is officially supported in the GR00T ecosystem via
so100_dualcam+new_embodiment. - The next chapter explains how to land the general VLA onto this specific embodiment, the SO-ARM.